
A pandas crosstab counts how often each pair of values shows up: call pd.crosstab(rows, columns) with two columns and you get a frequency table, one row per unique value of the first and one column per unique value of the second.
pd.crosstab(df["region"], df["category"])Every table below came from a real run on Python 3.12.5, pandas 3.0.6 and Matplotlib 3.11.2. The data is a small orders file: 12 Q1 2026 orders across three US regions, with amounts in USD.
In this tutorial, we’ll build count tables, add totals, sum and average dollar amounts, nest several columns, and check when crosstab beats pivot_table or groupby.
The sample orders data for these crosstab examples
Save this as orders.csv next to your script. If you’d rather build it in code, see creating a pandas DataFrame from a dict.
order_date,region,category,segment,amount
2026-01-05,East,Technology,Consumer,1249.99
2026-01-09,West,Furniture,Corporate,689.50
2026-01-14,East,Office Supplies,Consumer,45.20
2026-01-21,South,Technology,Corporate,899.00
2026-02-02,West,Technology,Consumer,329.99
2026-02-11,South,Furniture,Consumer,415.75
2026-02-17,East,Furniture,Corporate,1120.00
2026-02-25,West,Office Supplies,Corporate,88.40
2026-03-04,South,Technology,Consumer,189.99
2026-03-12,East,Technology,Corporate,2199.00
2026-03-19,West,Office Supplies,Corporate,64.75
2026-03-27,South,Technology,Consumer,159.99
Count combinations with a basic pd.crosstab
Pass the row labels first and the column labels second. Each cell is the number of orders with that region and category:
import pandas as pd

df = pd.read_csv("orders.csv")
print(pd.crosstab(df["region"], df["category"]))
Output:
category  Furniture  Office Supplies  Technology
region
East              1                1           2
South             1                0           3
West              1                2           1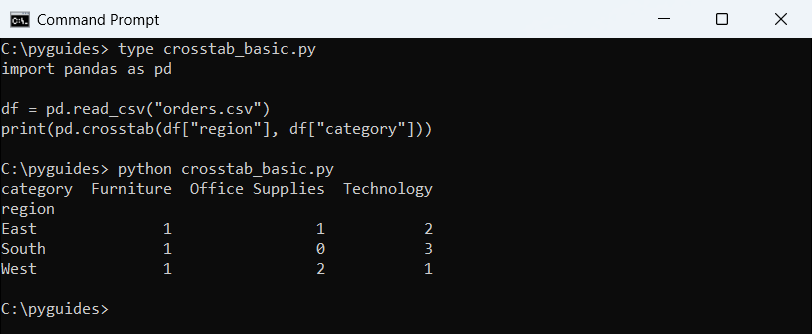
It’s the two-column version of counting unique values in a pandas column, and it saves you a groupby plus an unstack.
Add row and column totals with margins
margins=True adds a total row and column. I rename it with margins_name, and rownames/colnames label the axes:
import pandas as pd

df = pd.read_csv("orders.csv")
ct = pd.crosstab(df["region"], df["category"],
                 margins=True, margins_name="Total",
                 rownames=["Region"], colnames=["Category"])
print(ct)
Output:
Category  Furniture  Office Supplies  Technology  Total
Region
East              1                1           2      4
South             1                0           3      4
West              1                2           1      4
Total             3                3           6     12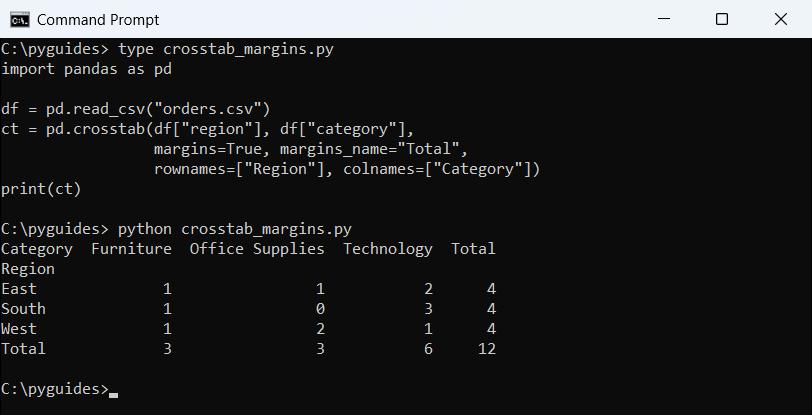
To check that grand total against the raw data, counting rows in a pandas DataFrame gives the same 12.
Sum or average a column with values and aggfunc
By default crosstab counts. Pass a numeric column as values plus an aggfunc such as "sum" or "mean", and you’ll get dollars instead of counts. You can’t use one without the other:
import pandas as pd

pd.set_option("display.precision", 2)   # show USD with 2 decimals
df = pd.read_csv("orders.csv")
sales = pd.crosstab(df["region"], df["category"], values=df["amount"],
                    aggfunc="sum", margins=True, margins_name="Total")
print(sales)
print()
print(pd.crosstab(df["region"], df["segment"], values=df["amount"], aggfunc="mean"))
Output:
category  Furniture  Office Supplies  Technology    Total
region
East        1120.00            45.20     3448.99  4614.19
South        415.75              NaN     1248.98  1664.73
West         689.50           153.15      329.99  1172.64
Total       2225.25           198.35     5027.96  7451.56

segment  Consumer  Corporate
region
East       647.60    1659.50
South      255.24     899.00
West       329.99     280.88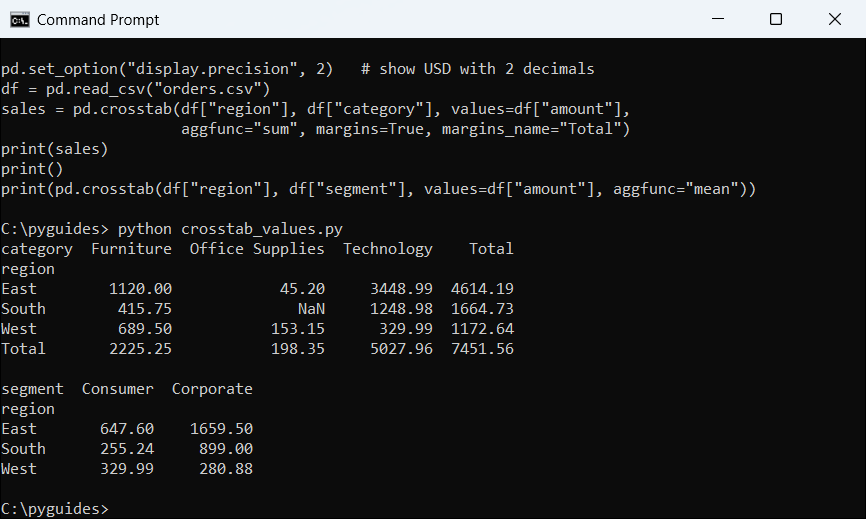
Any combination with no rows comes back as NaN, not 0; replacing NaN with 0 in pandas fixes that. For several functions at once, see pandas groupby aggregation functions.
Build a crosstab with multiple index columns
Pass a list of columns to get a MultiIndex, meaning nested row labels. Here rows are region plus segment, and the columns are the order month pulled from the date:
import pandas as pd

df = pd.read_csv("orders.csv", parse_dates=["order_date"])
month = df["order_date"].dt.strftime("%m-%b")
print(pd.crosstab([df["region"], df["segment"]], month))
Output:
order_date        01-Jan  02-Feb  03-Mar
region segment
East   Consumer        2       0       0
       Corporate       0       1       1
South  Consumer        0       1       2
       Corporate       1       0       0
West   Consumer        0       1       0
       Corporate       1       1       1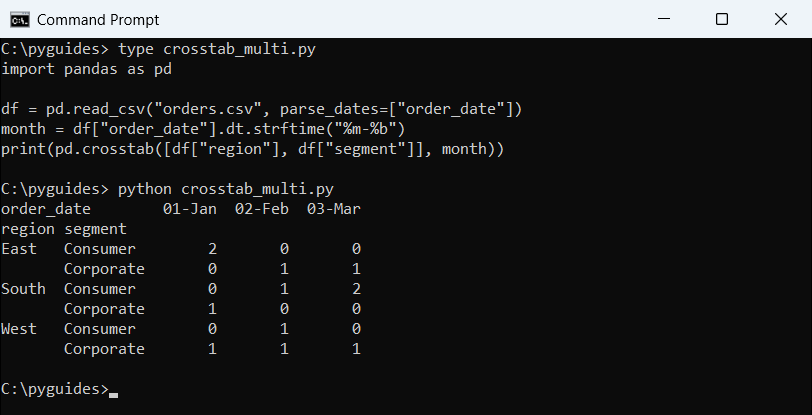
Lists work for columns too. Reading dates straight from the file is covered in reading a CSV file with pandas.
Show crosstab percentages with normalize
normalize="index" turns each row into shares that add up to 1; "columns" and True work the same way down columns or over the whole table:
import pandas as pd

df = pd.read_csv("orders.csv")
print(pd.crosstab(df["region"], df["category"], normalize="index").round(2))
Output:
category  Furniture  Office Supplies  Technology
region
East           0.25             0.25        0.50
South          0.25             0.00        0.75
West           0.25             0.50        0.25
Each region’s row adds up to 1.0. I go deeper, with margins and formatting, in percentage normalization using crosstab in pandas.
When should you use crosstab instead of pivot_table or groupby?
All three give the same sums here. I’ve checked it, and both comparisons print True:
import pandas as pd

df = pd.read_csv("orders.csv")
ct = pd.crosstab(df["region"], df["category"], values=df["amount"], aggfunc="sum")
pt = df.pivot_table(index="region", columns="category", values="amount", aggfunc="sum")
gb = df.groupby(["region", "category"])["amount"].sum().unstack()

print(ct.equals(pt), ct.equals(gb))
Output:
True TrueReach for crosstab for counts and for arrays or Series that aren’t in one DataFrame. Use a pandas pivot table when the data’s already a DataFrame, and groupby in pandas for long, tidy results.
Plot a pandas crosstab as a stacked bar chart
A crosstab is already a DataFrame, so .plot() draws one bar per row and stacks the columns:
import pandas as pd
import matplotlib.pyplot as plt

df = pd.read_csv("orders.csv")
ct = pd.crosstab(df["region"], df["category"], values=df["amount"], aggfunc="sum")

ax = ct.plot(kind="bar", stacked=True, figsize=(8, 4.5), rot=0)
ax.set_ylabel("Sales (USD)")
ax.set_title("Q1 2026 sales by region and category")
plt.tight_layout()
plt.show()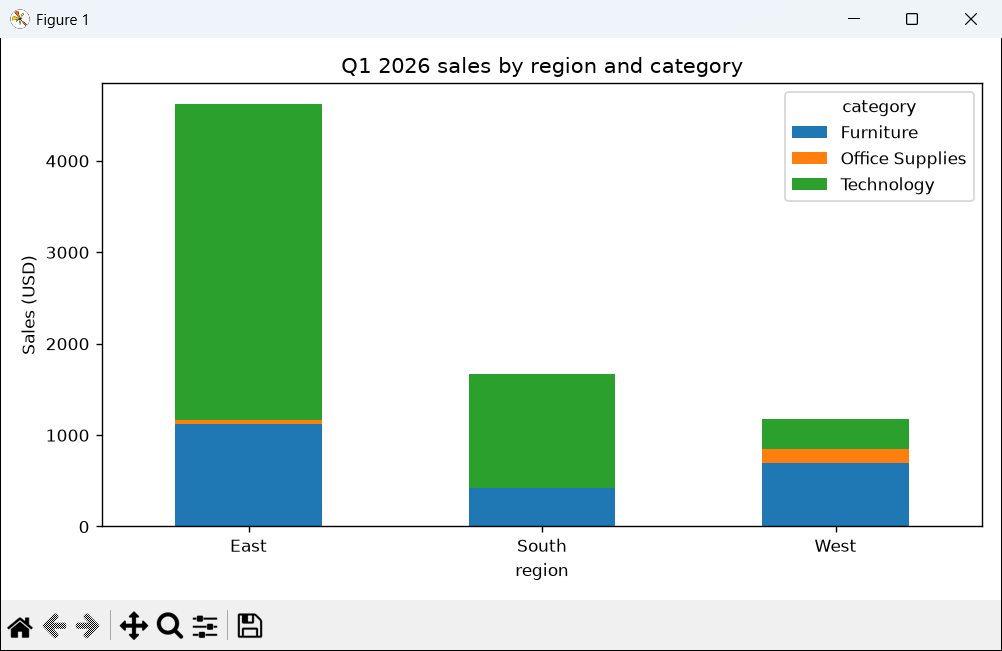
More chart types, including heatmaps, are in creating plots using pandas crosstab.
Next, you could try one of these:
- Stacked bar plots in pandas
- Sort a pandas DataFrame by multiple columns
- Get unique values in a pandas DataFrame
- Count duplicates in a pandas DataFrame
Frequently asked questions
What does pd.crosstab do?
It builds a frequency table: how often each combination of two or more factors occurs.
How do I add totals to a pandas crosstab?
Pass margins=True; rename the label with margins_name="Total".
Can crosstab sum a column instead of counting?
Yes. Pass values=df["amount"] together with aggfunc="sum".
Why does my crosstab show NaN?
With values, empty combinations become NaN. Add .fillna(0).
Is crosstab faster than pivot_table?
Not really; crosstab calls pivot_table internally. Pick whichever reads better.
Where are all the crosstab parameters documented?
See pandas.crosstab in the pandas docs.

Bijay Kumar is a 13-time Microsoft MVP with more than 18 years in software development, and the founder of Python Guides and TSinfo Technologies. He started out building .NET and SharePoint solutions at HP, TCS and KPIT before moving into Python, machine learning and AI, and he also builds web apps with TypeScript and React. He writes the tutorials here himself, and every example is run before publishing so you see the real output. More about Bijay · Microsoft MVP profile · LinkedIn