
np.sum adds up the values in a NumPy array, either all of them or along one axis:
np.sum(a)            # every element
np.sum(a, axis=0)    # down the columns
np.sum(a, axis=1)    # across the rows

a.sum()              # the method form, identical
The axis argument is what people come for, and the rule is short: the axis you name is the one that disappears from the result.
All figures below are real runs on Python 3.12.5, NumPy 2.5.3.
Using np.sum in Python
Function or method, it makes no difference which you use:
import numpy as np

a = np.array([[1, 2, 3],
              [4, 5, 6]])

print("whole array :", np.sum(a))
print("method form :", a.sum(), "  identical")

print()
print("down the columns, axis=0:", a.sum(axis=0))
print("across the rows, axis=1 :", a.sum(axis=1))
Output:
whole array : 21
method form : 21   identical

down the columns, axis=0: [5 7 9]
across the rows, axis=1 : [ 6 15]
np.sum(a) and a.sum() call the same code. The function form also accepts plain Python lists, which the method form obviously cannot.
Summing a whole array returns a NumPy scalar rather than a plain int. It behaves like one for arithmetic, so this rarely matters.
What the numpy sum axis argument does
Naming an axis collapses it. A (2, 3) array summed along axis=1 becomes shape (2,):
import numpy as np

a = np.arange(1, 7).reshape(2, 3)
print(a)

print()
# the axis you name is the one that disappears
print("a.sum()        ->", a.sum(), "        shape ()")
print("a.sum(axis=0)  ->", a.sum(axis=0), " shape", a.sum(axis=0).shape)
print("a.sum(axis=1)  ->", a.sum(axis=1), "   shape", a.sum(axis=1).shape)

print()
# keepdims leaves a length-1 axis behind so broadcasting still lines up
print("keepdims=False shape:", a.sum(axis=1).shape)
print("keepdims=True  shape:", a.sum(axis=1, keepdims=True).shape)

print()
print("that matters for normalising:")
print(a / a.sum(axis=1, keepdims=True))
Output:
[[1 2 3]
 [4 5 6]]

a.sum()        -> 21         shape ()
a.sum(axis=0)  -> [5 7 9]  shape (3,)
a.sum(axis=1)  -> [ 6 15]    shape (2,)

keepdims=False shape: (2,)
keepdims=True  shape: (2, 1)

that matters for normalising:
[[0.16666667 0.33333333 0.5       ]
 [0.26666667 0.33333333 0.4       ]]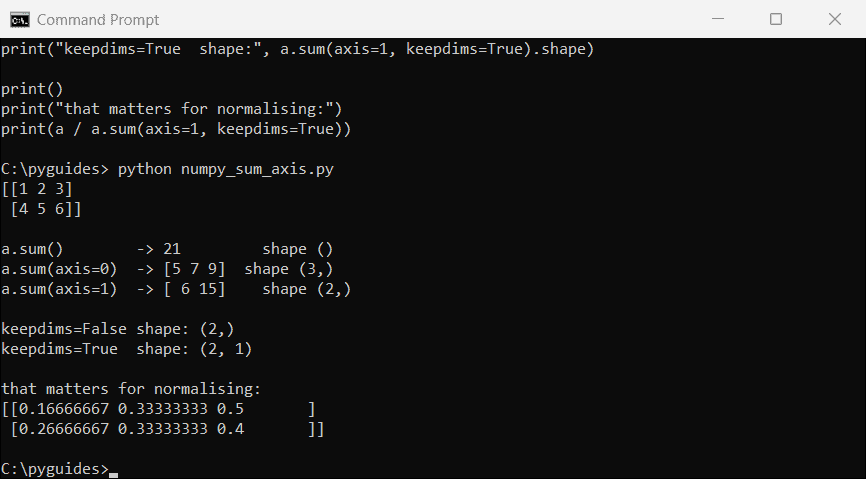
axis=0 gives three column totals, axis=1 gives two row totals.| Call | Result | Shape |
|---|---|---|
a.sum() | One number | () |
a.sum(axis=0) | One per column | (3,) |
a.sum(axis=1) | One per row | (2,) |
a.sum(axis=1, keepdims=True) | One per row | (2, 1) |
keepdims=True is the one worth remembering. It leaves a length-1 axis in place so the result still broadcasts against the original array.
That is exactly what you need to turn rows into percentages, as the last line of the example shows. The same axis rule governs every reduction, including the ones in NumPy 3D arrays.
Does np.sum overflow on integers?
Not by default, despite what a lot of advice claims. NumPy widens the accumulator for you:
import numpy as np

big = np.full(100_000, 100_000, dtype=np.int32)

# NumPy promotes the accumulator, so the default is SAFE
print("array dtype        :", big.dtype)
print("big.sum()          :", big.sum(), " dtype", big.sum().dtype)
print("true value         :", 100_000 * 100_000)

print()
# forcing the accumulator back to int32 overflows, silently
print("big.sum(dtype=np.int32):", big.sum(dtype=np.int32), " <- WRONG, and no warning")
Output:
array dtype        : int32
big.sum()          : 10000000000  dtype int64
true value         : 10000000000

big.sum(dtype=np.int32): 1410065408  <- WRONG, and no warning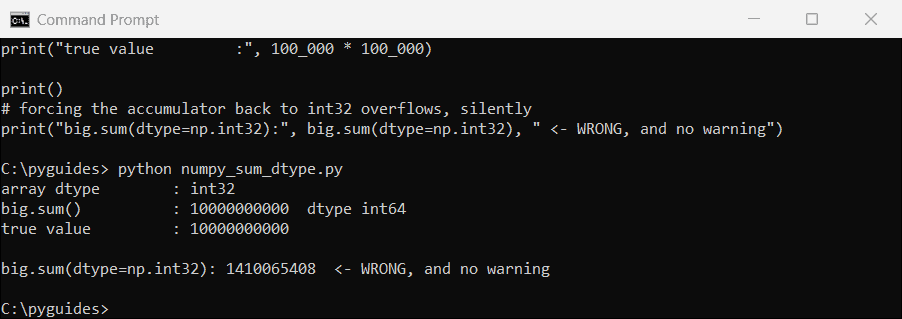
dtype=np.int32 is what breaks it.Summing an int32 array returns an int64, so a total of ten billion comes out exactly right.
Force the accumulator back down with dtype=np.int32 and you get 1410065408, silently and with no warning at all.
So the rule is simple: leave dtype alone unless you have a specific reason, and never narrow it to save memory on the result of a sum.
NumPy sum of squares
A sum of squares is just np.sum applied to a squared array, and there are three ways to write it:
import numpy as np
import timeit

v = np.random.default_rng(0).random(1000)

# three ways to write a sum of squares
a = np.sum(v ** 2)
b = np.dot(v, v)
c = np.einsum("i,i->", v, v)

print("np.sum(v ** 2) :", round(a, 9))
print("np.dot(v, v)   :", round(b, 9))
print("np.einsum      :", round(c, 9))
print("all equal      :", np.allclose([a, b], c))

print()
t_sum = timeit.timeit(lambda: np.sum(v ** 2), number=20_000)
t_dot = timeit.timeit(lambda: np.dot(v, v), number=20_000)
print(f"np.sum(v ** 2) {t_sum * 1000:>6.0f} ms")
print(f"np.dot(v, v)   {t_dot * 1000:>6.0f} ms   faster, because it never builds v ** 2")
Output:
np.sum(v ** 2) : 348.18123909
np.dot(v, v)   : 348.18123909
np.einsum      : 348.18123909
all equal      : True

np.sum(v ** 2)     38 ms
np.dot(v, v)       11 ms   faster, because it never builds v ** 2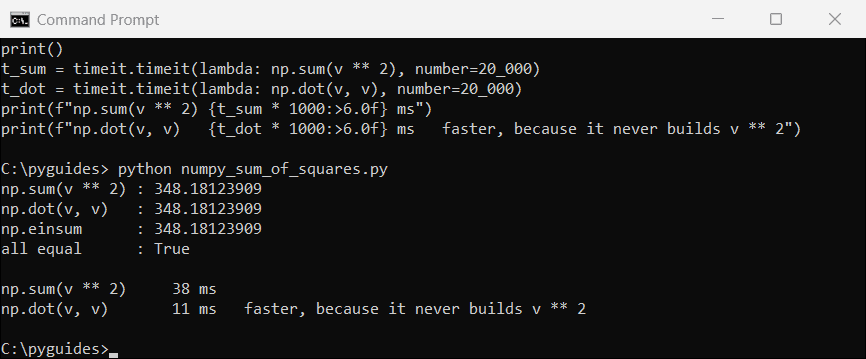
np.dot is the quickest of the three.np.sum(v ** 2) is the clearest to read, and it is the right default.
np.dot(v, v) is faster because it never builds the intermediate squared array. It multiplies and accumulates in one pass.
On a thousand elements the difference is tiny. On a million, inside a loop, it is worth having.
Sum of squares along an axis
For 2D data you usually want one total per row, which is where the axis argument earns its keep:
import numpy as np

data = np.array([[3, 4],
                 [6, 8]])

# sum of squares per row is the squared length of each row vector
print("per row  :", np.sum(data ** 2, axis=1))
print("per col  :", np.sum(data ** 2, axis=0))
print("everything:", np.sum(data ** 2))

print()
# which is where Euclidean distance comes from
print("row lengths:", np.sqrt(np.sum(data ** 2, axis=1)))
print("same as norm:", np.linalg.norm(data, axis=1))
Output:
per row  : [ 25 100]
per col  : [45 80]
everything: 125

row lengths: [ 5. 10.]
same as norm: [ 5. 10.]
The square root of a row’s sum of squares is that row’s length, which is why this pattern turns up everywhere in geometry and machine learning.
np.linalg.norm(data, axis=1) does the same thing in one call and is clearer about intent. Use it when length is what you actually mean.
np.sum vs Python’s built-in sum
Both work on a NumPy array, and one of them is dramatically faster:
import numpy as np
import timeit

arr = np.arange(1_000_000)

py = timeit.timeit(lambda: sum(arr), number=3) / 3
np_ = timeit.timeit(lambda: np.sum(arr), number=3) / 3

print(f"python sum(arr) : {py * 1000:>8.1f} ms")
print(f"np.sum(arr)     : {np_ * 1000:>8.2f} ms")
print(f"\nnp.sum is about {py / np_:.0f}x faster on a NumPy array")

print()
print("both give the same answer:", sum(arr) == np.sum(arr))
Output:
python sum(arr) :     38.5 ms
np.sum(arr)     :     0.42 ms

np.sum is about 92x faster on a NumPy array

both give the same answer: True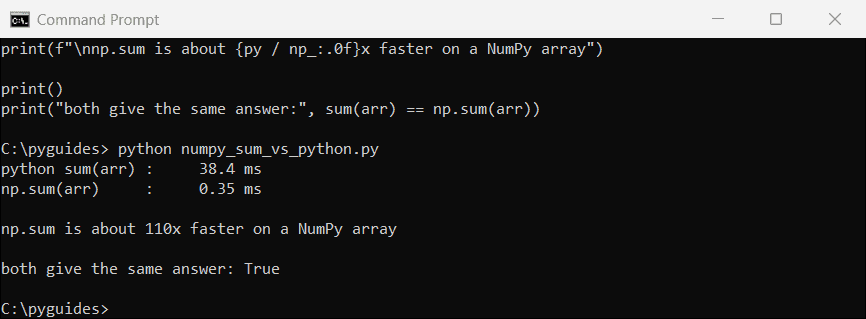
Python’s sum pulls each element out of the array and converts it to a Python object one at a time. np.sum stays in compiled code throughout.
The rule of thumb: if the data is already in a NumPy array, never use the built-in sum on it.
Going the other way, the built-in is fine for plain Python lists. Converting a short list to an array just to sum it costs more than it saves. See NumPy array creation for the conversion cost.
Summing arrays with NaN or a condition
A single NaN turns the whole total into NaN, which is technically correct and rarely what you want:
import numpy as np

values = np.array([1.0, 2.0, np.nan, 4.0])

print("np.sum    :", np.sum(values), "  one NaN poisons the whole total")
print("np.nansum :", np.nansum(values), "  NaNs treated as zero")

print()
# summing only the values that pass a test
data = np.array([5, -3, 8, -1, 10])
print("positives only:", np.sum(data, where=data > 0))
print("or with a mask:", data[data > 0].sum())

print()
print("empty array   :", np.sum([]), "  0.0, not an error")
Output:
np.sum    : nan   one NaN poisons the whole total
np.nansum : 7.0   NaNs treated as zero

positives only: 23
or with a mask: 23

empty array : 0.0 0.0, not an errornp.nansum— treats NaN as zero.np.sum(a, where=a > 0)— sums only the elements that pass a test.a[a > 0].sum()— the same result by filtering first.np.sum([])— returns0.0rather than raising.
where= avoids building the filtered copy, so it is the better choice on large arrays. For small ones the difference is not worth the extra syntax.
Common np.sum mistakes
| Symptom | Cause | Fix |
|---|---|---|
Result is nan | A NaN in the data | Use np.nansum |
| Wrong axis totals | Confused axis=0 and axis=1 | The named axis disappears |
| Broadcasting error after summing | Lost a dimension | Add keepdims=True |
| A negative or nonsense total | Narrowed dtype | Leave the default accumulator |
| Very slow on a big array | Used the built-in sum | Use np.sum |
Related NumPy calculation guides:
- NumPy 3D arrays and axes
- NumPy empty arrays
- NumPy linspace
- NumPy data types
- Find unique values in a NumPy array
- Factorials with NumPy
Frequently asked questions
What does np.sum do in NumPy?
It adds the elements of an array, optionally along one axis. The full signature is in the numpy.sum reference.
What is the difference between axis=0 and axis=1 in np.sum?
axis=0 sums down the columns and axis=1 sums across the rows. In both cases the axis you name is removed from the result’s shape.
How do I calculate a sum of squares in NumPy?
np.sum(v ** 2) is the clearest. np.dot(v, v) gives the same answer faster because it skips the intermediate array.
Does np.sum overflow with integers?
Not by default. NumPy promotes the accumulator to int64. It only overflows if you force a narrower dtype, and then it does so silently.
What does keepdims=True do?
It keeps the summed axis as a length-1 dimension, so the result still broadcasts against the original array. Useful for normalising rows or columns.
Why is my np.sum returning nan?
One of the values is NaN, and NaN propagates through addition. Use np.nansum to ignore them.
Is np.sum faster than Python’s sum?
On a NumPy array, by a very wide margin, because it stays in compiled code instead of converting each element to a Python object.

Bijay Kumar is a 13-time Microsoft MVP with more than 18 years in software development, and the founder of Python Guides and TSinfo Technologies. He started out building .NET and SharePoint solutions at HP, TCS and KPIT before moving into Python, machine learning and AI, and he also builds web apps with TypeScript and React. He writes the tutorials here himself, and every example is run before publishing so you see the real output. More about Bijay · Microsoft MVP profile · LinkedIn