
scipy.stats.multivariate_normal is SciPy’s multivariate normal (Gaussian) distribution. Give it a mean vector and a covariance matrix, then call pdf() for the density, cdf() for probabilities, rvs() for random samples and fit() to estimate the parameters from data. This guide explains each method with a complete, runnable example and checks the results against simulation.
Every example is self-contained and was run with Python 3.12.5, NumPy 2.5.3, SciPy 1.18.1 and Matplotlib 3.11.2. The plots are produced by the code shown. For the full reference, see the SciPy multivariate_normal reference.
Quick start
import numpy as np
from scipy.stats import multivariate_normal

mean = [0, 0]
cov = [[1.0, 0.8],
       [0.8, 1.0]]          # variances on the diagonal, covariance off it

rv = multivariate_normal(mean=mean, cov=cov)   # a "frozen" distribution

print(rv.pdf([0, 0]))                          # density at one point
print(rv.pdf([[0, 0], [1, 1], [1, -1]]))       # several points at once
print(rv.rvs(size=3, random_state=42))         # 3 random samples
Output:
0.26525823848649227
[0.26525824 0.15219282 0.0017873 ]
[[-0.42750141 -0.51494743]
 [-1.09607563 -0.13282697]
 [ 0.296178    0.14809679]]
pdf() and rvs() run in the Command Prompt.multivariate_normal(mean, cov) returns a frozen distribution: the mean and covariance are stored, so you only pass the points. You can also call the methods directly, for example multivariate_normal.pdf(x, mean=mean, cov=cov).
| Method | Returns |
|---|---|
pdf(x) / logpdf(x) | Probability density (or its log) at each point |
cdf(x, lower_limit=None) / logcdf(x) | Probability that every coordinate is ≤ x (or inside a box) |
rvs(size, random_state) | Random samples, shape (size, d) |
fit(data) | Estimated mean and covariance from data |
marginal(dims) | Distribution of a subset of the dimensions |
entropy() | Differential entropy |
Mean and covariance: what the parameters mean
The mean is the centre, one number per dimension. The covariance matrix is d × d: the diagonal holds each variable’s variance, and the off-diagonal values say how two variables move together. It must be symmetric and positive semi-definite. If you know standard deviations and correlations, build it like this:
import numpy as np

std = np.array([2.0, 0.5])            # standard deviations of x and y
corr = np.array([[1.0, -0.6],         # correlation matrix
                 [-0.6, 1.0]])

cov = corr * np.outer(std, std)       # covariance = correlation x std_i x std_j
print(cov)
print("symmetric:", np.allclose(cov, cov.T))
print("eigenvalues:", np.linalg.eigvalsh(cov))   # all > 0 means positive definite
Output:
[[ 4.   -0.6 ]
 [-0.6   0.25]]
symmetric: True
eigenvalues: [0.15633929 4.09366071]
The shape of the distribution follows directly from the covariance matrix:
import numpy as np
import matplotlib.pyplot as plt
from scipy.stats import multivariate_normal

x, y = np.mgrid[-3:3:0.02, -3:3:0.02]
pos = np.dstack((x, y))                      # shape (300, 300, 2): one (x, y) pair per grid point

covs = {"independent\n[[1, 0], [0, 1]]": [[1, 0], [0, 1]],
        "positive correlation\n[[1, 0.8], [0.8, 1]]": [[1, 0.8], [0.8, 1]],
        "negative correlation\n[[1, -0.8], [-0.8, 1]]": [[1, -0.8], [-0.8, 1]],
        "different variances\n[[2, 0], [0, 0.3]]": [[2, 0], [0, 0.3]]}

fig, axes = plt.subplots(1, 4, figsize=(14, 3.8))
for ax, (title, cov) in zip(axes, covs.items()):
    ax.contourf(x, y, multivariate_normal([0, 0], cov).pdf(pos), levels=12, cmap="viridis")
    ax.set_title(title, fontsize=10)
    ax.set_aspect("equal")
fig.tight_layout()
plt.show()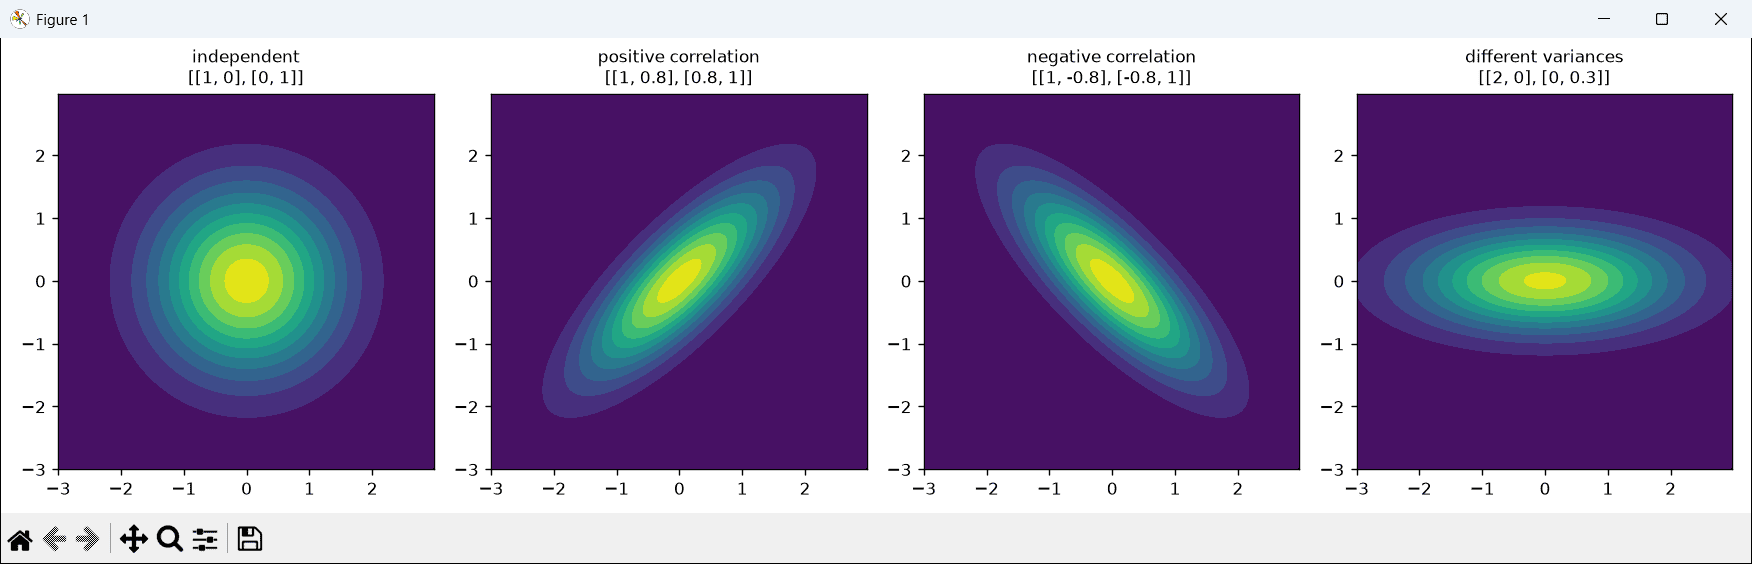
pdf() and logpdf()
pdf() takes one point or an array of points with the dimension in the last axis, which is why the plots above pass np.dstack((x, y)). In many dimensions the density becomes tiny and underflows to zero; logpdf() stays accurate, so use it for likelihoods:
import numpy as np
from scipy.stats import multivariate_normal

d = 1000                                 # a 1000-dimensional distribution
rv = multivariate_normal(mean=np.zeros(d), cov=np.eye(d))
x = np.full(d, 1.0)

print(rv.pdf(x))        # underflows to 0.0
print(rv.logpdf(x))     # the log of the density is still accurate
Output:
0.0
-1418.9385332046727
rvs(): draw random samples
rvs() returns an array of shape (size, d). Pass random_state (an integer or a NumPy Generator) to get the same samples every time:
import numpy as np
from scipy.stats import multivariate_normal

mean = [5, 10]
cov = [[4, 1.5],
       [1.5, 1]]

samples = multivariate_normal.rvs(mean=mean, cov=cov, size=100_000, random_state=0)

print(samples.shape)
print(samples.mean(axis=0).round(3))          # close to [5, 10]
print(np.cov(samples, rowvar=False).round(3)) # close to cov
Output:
(100000, 2)
[ 4.998 10.004]
[[3.989 1.492]
 [1.492 0.993]]
With 100,000 samples the sample mean and covariance are within a few thousandths of the true values. Here is the density with 400 samples on top:
import numpy as np
import matplotlib.pyplot as plt
from scipy.stats import multivariate_normal

rv = multivariate_normal(mean=[1, 2], cov=[[2.0, 0.9], [0.9, 1.0]])

x, y = np.mgrid[-4:6:0.02, -2:6:0.02]
density = rv.pdf(np.dstack((x, y)))
samples = rv.rvs(size=400, random_state=1)

fig, ax = plt.subplots(figsize=(6, 4.5))
cs = ax.contourf(x, y, density, levels=15, cmap="Blues")
ax.scatter(samples[:, 0], samples[:, 1], s=6, color="tab:orange", alpha=0.7, label="400 samples")
fig.colorbar(cs, label="pdf")
ax.set_xlabel("x")
ax.set_ylabel("y")
ax.legend(loc="upper left")
plt.show()
cdf(): probabilities
cdf(x) gives the probability that every coordinate is at most the value in x. With lower_limit you get the probability of a box. The result is computed numerically, so it’s accurate to about five decimal places by default; the check with a million samples agrees:
import numpy as np
from scipy.stats import multivariate_normal

rv = multivariate_normal(mean=[0, 0], cov=[[1, 0.5], [0.5, 1]])

# P(X <= 1 and Y <= 1)
p = rv.cdf([1, 1])
print(round(p, 4))

# P(-1 <= X <= 1 and -1 <= Y <= 1): a rectangle, using lower_limit
p_box = rv.cdf([1, 1], lower_limit=[-1, -1])
print(round(p_box, 4))

# check both with 1,000,000 random samples
s = rv.rvs(size=1_000_000, random_state=0)
print(round(np.mean((s[:, 0] <= 1) & (s[:, 1] <= 1)), 4))
print(round(np.mean((np.abs(s) <= 1).all(axis=1)), 4))
Output:
0.7452
0.498
0.7453
0.4978
fit(): estimate mean and covariance from data
multivariate_normal.fit() returns the maximum-likelihood mean and covariance of your data (rows are observations, columns are variables):
import numpy as np
from scipy.stats import multivariate_normal

true_mean = [170, 70]                       # height (cm), weight (kg)
true_cov = [[50, 30],
            [30, 60]]
data = multivariate_normal.rvs(true_mean, true_cov, size=5000, random_state=7)

mean_hat, cov_hat = multivariate_normal.fit(data)
print(mean_hat.round(2))
print(cov_hat.round(2))
Output:
[170.08  69.98]
[[49.81 28.73]
 [28.73 57.41]]
The estimates are close to the true values [170, 70] and [[50, 30], [30, 60]]. Use fix_mean or fix_cov to keep one of them fixed.
marginal(): drop dimensions
The marginal of a multivariate normal is again normal: just keep the matching rows and columns of the mean and covariance. marginal() does this for you:
from scipy.stats import multivariate_normal

rv = multivariate_normal(mean=[1, 2, 3],
                         cov=[[2.0, 0.3, 0.5],
                              [0.3, 1.0, 0.2],
                              [0.5, 0.2, 3.0]])

m = rv.marginal([0, 2])            # keep dimensions 0 and 2, drop dimension 1
print(m.mean)
print(m.cov)
Output:
[1. 3.]
[[2.  0.5]
 [0.5 3. ]]
Conditional distribution
SciPy has no conditional method, but for two variables the formula is short: the conditional mean shifts by cov_xy / var_x × (x − mean_x) and the variance shrinks. The simulation below confirms it:
import numpy as np
from scipy.stats import multivariate_normal

mean = np.array([170.0, 70.0])      # height, weight
cov = np.array([[50.0, 30.0],
                [30.0, 60.0]])

# distribution of weight given height = 180
h = 180
cond_mean = mean[1] + cov[1, 0] / cov[0, 0] * (h - mean[0])
cond_var = cov[1, 1] - cov[1, 0] ** 2 / cov[0, 0]
print(f"weight | height=180 ~ N({cond_mean:.2f}, {cond_var:.2f})")

# check with samples whose height is close to 180
s = multivariate_normal.rvs(mean, cov, size=2_000_000, random_state=3)
near = s[np.abs(s[:, 0] - h) < 0.5, 1]
print(f"from samples:        mean {near.mean():.2f}, variance {near.var():.2f}")
Output:
weight | height=180 ~ N(76.00, 42.00)
from samples:        mean 76.00, variance 41.56
Practical example: find outliers with the Mahalanobis distance
For normally distributed data, the squared Mahalanobis distance follows a chi-squared distribution with d degrees of freedom. Points above its 99.9th percentile are unusual. Unlike a plain distance from the centre, it takes the correlation into account. I added three far-away points to 300 correlated ones:
import numpy as np
import matplotlib.pyplot as plt
from scipy.stats import chi2, multivariate_normal

data = multivariate_normal.rvs([0, 0], [[1, 0.7], [0.7, 1]], size=300, random_state=5)
data = np.vstack([data, [[2.5, -2.0], [-2.2, 2.4], [3.2, 3.4]]])   # 3 far-away points

mean_hat, cov_hat = multivariate_normal.fit(data)
diff = data - mean_hat
d2 = np.einsum("ij,jk,ik->i", diff, np.linalg.inv(cov_hat), diff)  # squared Mahalanobis distance
limit = chi2.ppf(0.999, df=2)                                       # 99.9% cut-off for 2 dimensions
outliers = d2 > limit

print(f"cut-off: {limit:.2f}")
print("outliers:", np.round(data[outliers], 2).tolist())

fig, ax = plt.subplots(figsize=(6, 4.5))
ax.scatter(*data[~outliers].T, s=8, label="normal points")
ax.scatter(*data[outliers].T, s=60, color="red", marker="x", label="outliers")
ax.set_aspect("equal")
ax.legend()
plt.show()
Output:
cut-off: 13.82
outliers: [[2.5, -2.0], [-2.2, 2.4]]
Common errors
import numpy as np
from scipy.stats import multivariate_normal

bad_cov = [[1, 2],
           [2, 1]]                       # not positive semi-definite
try:
    multivariate_normal(mean=[0, 0], cov=bad_cov)
except ValueError as err:
    print("ValueError:", err)

singular = [[1, 1],
            [1, 1]]                      # x and y always equal: singular
try:
    multivariate_normal(mean=[0, 0], cov=singular)
except np.linalg.LinAlgError as err:
    print("LinAlgError:", err)

rv = multivariate_normal(mean=[0, 0], cov=singular, allow_singular=True)
print(rv.pdf([0.5, 0.5]), rv.pdf([0.5, -0.5]))

try:
    multivariate_normal(mean=[0, 0, 0], cov=np.eye(2))
except ValueError as err:
    print("ValueError:", err)
Output (the real messages from SciPy 1.18):
ValueError: The input matrix must be symmetric positive semidefinite.
LinAlgError: When `allow_singular is False`, the input matrix must be symmetric positive definite.
0.24894777997569387 0.0
ValueError: Dimension mismatch: array 'cov' is of shape (2, 2), but 'mean' is a vector of length 3.- Not positive semi-definite: the covariance matrix is impossible (e.g. a correlation above 1). Rebuild it from standard deviations and valid correlations.
- Singular matrix: one variable is an exact linear combination of others. Pass
allow_singular=True; the density is then zero outside the line or plane the data lives on. - Dimension mismatch:
meanmust have length d andcovshape (d, d).
More SciPy: SciPy tutorials
Further reading on SciPy and statistics:
- SciPy stats tutorial
- scipy.stats.norm explained
- Fit a distribution with scipy.stats
- scipy.stats.zscore
Frequently asked questions
How do I use scipy.stats.multivariate_normal?
Create a distribution with rv = multivariate_normal(mean=[0, 0], cov=[[1, 0.5], [0.5, 1]]), then call rv.pdf(x), rv.cdf(x) or rv.rvs(size=100).
What shape should x have for pdf()?
The last axis must be the dimension: one point is [x, y], many points are an array of shape (n, 2), and a grid for plotting is np.dstack((X, Y)).
How do I generate random samples from a multivariate normal distribution?
Use multivariate_normal.rvs(mean, cov, size=n, random_state=0), or np.random.default_rng().multivariate_normal(mean, cov, size=n) in NumPy.
Why does pdf() return 0?
In many dimensions the density is smaller than the smallest float and underflows. Use logpdf() instead.
Why do I get ‘the input matrix must be positive semi-definite’?
The covariance matrix isn’t valid (for example, a correlation larger than 1 or a typo). Check it is symmetric and that np.linalg.eigvalsh(cov) has no negative values.

Bijay Kumar is an experienced Python and AI professional who enjoys helping developers learn modern technologies through practical tutorials and examples. His expertise includes Python development, Machine Learning, Artificial Intelligence, automation, and data analysis using libraries like Pandas, NumPy, TensorFlow, Matplotlib, SciPy, and Scikit-Learn. At PythonGuides.com, he shares in-depth guides designed for both beginners and experienced developers. More about us.